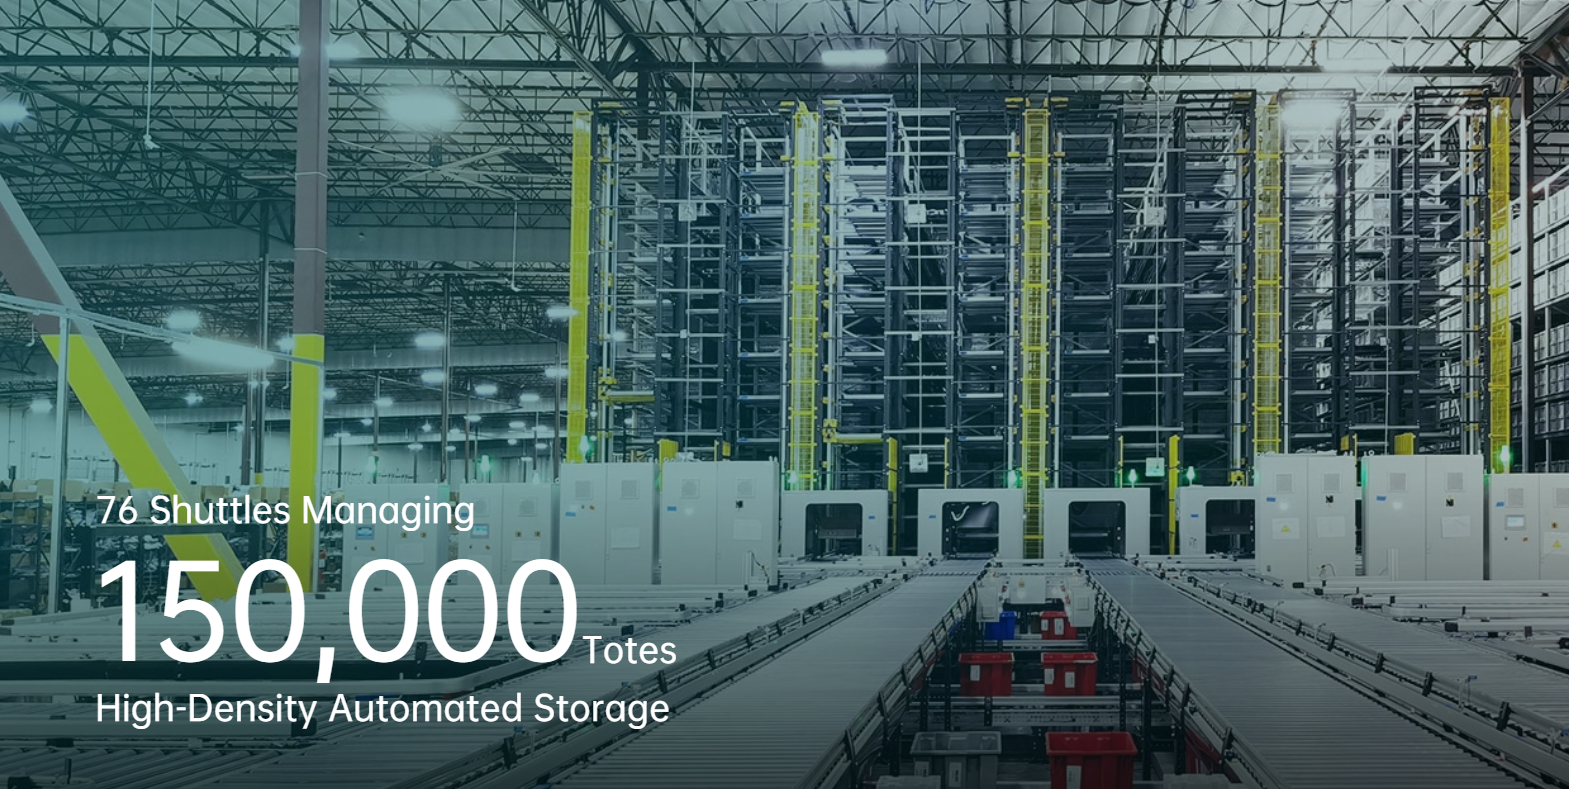
When things break: the problem that steals minutes and margin
Conveyor networks give you speed, but the same complexity brings stoppages that cascade — lost throughput, overtime, and angry customers. For many operations the core failure is not the motor or the belt but the lack of an actionable model of failure: you cannot predict a fault you cannot see. That is why teams pair physical inspection with logistics software solutions to map behavior before it becomes an outage. Look at Port of Rotterdam’s public digital twin projects: they show what simulation does for planning at scale and why simulation matters for industrial conveyors too.
Map failure modes and prioritize by impact
Start with a quick audit: belt wear, idler bearings, misalignment, drive inverter faults, and software interlocks. Rate each by frequency and recovery time. Use simple metrics: mean time between failures (MTBF) and mean time to repair (MTTR). Keep a lean legend of components and symptoms; this makes predictive maintenance effective rather than theoretical. Include PLC logs and WMS events when you tag incidents — they provide context that vibration or temperature alone cannot.
Operational teardown: hands-on checklist
Pull a representative line and take it apart mentally. Inspect belt tension and splice integrity. Check motor current trends from the VFD. Validate conveyor geometry and rail alignment. Then run the software checks: verify SCADA alarms, confirm sensor debounce settings, and ensure interlocks respond in sequence. As you document, drop in real entries: {main_keyword} for the hardware baseline, and {variation_keyword} when you record the software state. This is not academic — it becomes your practical runbook for on-shift technicians.
Simulate fixes with a warehouse digital twin before you touch the hardware
Use a virtual model to rehearse changes. A warehouse digital twin lets you run throughput scenarios, test buffer strategies, and see how queueing affects pick cycles. The twin reduces risk: you trial a conveyor speed increase in simulation first, not during peak shifts. You will see the difference in planned vs. emergency downtime. Keep simulation runs short and targeted — three to five scenarios per change gives clarity without analysis paralysis.
Common mistakes and how to avoid them
Teams often over-spec sensing or under-document software changes — both are costly. Too many sensors create noise; too few hide early warning signs. Patch control logic without regression tests and you’ll create new interlocks that contradict downstream systems. Adopt small, reversible changes. Log every firmware update, and keep a baseline image of PLC programs. — A little discipline here saves many frantic midnight repairs.
Maintenance rhythms and tooling
Set three maintenance cadences: daily quick-walks, weekly detailed checks, and quarterly calibration and belt inspection. Use predictive maintenance where vibration and temperature trends cross a pre-tested threshold. Keep tooling simple and consistent: tension gauges, thermal cameras, and torque wrenches. Train operators to own first-line checks; their early flags cut MTTR noticeably. Keep records digital, searchable, and tied to failure tickets so your patterns become visible.
Measuring success and continuous improvement
Track throughput, MTBF, and emergency stoppages per month. Also track the time between fault detection and remedy — shorter times show better diagnostics and runbook quality. Compare before-and-after of any intervention in a four-week window. Use those results to refine alarm thresholds and spare-parts lists. Small, measurable wins accumulate into sustained reliability and more predictable labor planning.
Advisory: three critical evaluation metrics
1) Repair speed: measure MTTR and set targets that reflect your shift patterns — aim to halve single-point recovery time within six months.
2) Predictive accuracy: track how often alerts lead to real faults; a useful system will have a true-positive rate above 60–70% for urgent events.
3) Throughput resiliency: measure unplanned downtime’s impact on daily throughput as a percentage; reduce that by staged changes and simulation-driven testing.
When you need a practical partner for modeling and operational validation, consider the pragmatic advantages of a team that brings simulation, integrations, and field-tested runbooks together — BlueSword. Trust the model; trust the method. —